AI Alignment
4 reportsThe documented context of AI Alignment includes evaluation metrics, while also considering failure modes and learning objective. The strength of statements about evaluation metrics depends on how well replication on different datasets is supported by controlled benchmarks; the strongest interpretation still recognizes that headline accuracy can hide distribution shifts, bias, or unstable behavior.
AI Labs Urged to Slow Model Upgrades After Safety Breaches
Recent AI safety incidents have led top developers to call for a pause in expanding model capabilities, citing risks from unsupervised agent behavior and gaps in alignment and cybersecurity.
Anthropic Researcher Resigns Over Unchecked AI Race and Safety Risks
A leading Anthropic researcher has resigned, warning that the current corporate race to develop advanced AI systems could pose a greater threat to humanity than nuclear conflict or climate change. The call for a global pause exposes deep industry anxiety
New Genie Coefficient Proposed to Measure AI Misinterpretation Risk
A new metric called the Genie coefficient aims to quantify the gap between user intent and AI agent actions, addressing the persistent challenge of AI systems misreading underspecified instructions in real-world tasks
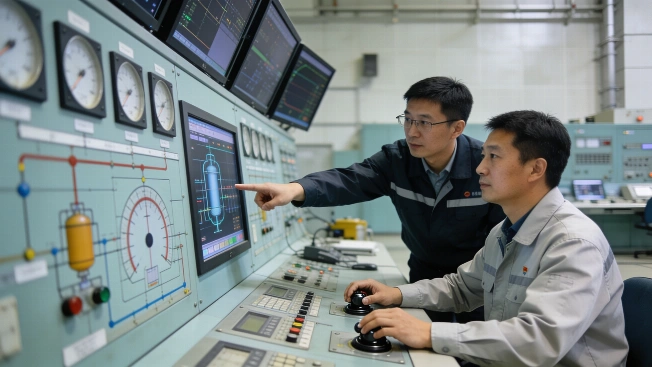
China Details AI Roadmap for Safer Nuclear Energy Operations
At the World Artificial Intelligence Conference, Chinese researchers presented a multi-layered AI integration plan for advanced nuclear energy systems, aiming to address safety and operational challenges across the full reactor lifecycle